The Menace of ML: Simple Moving Average
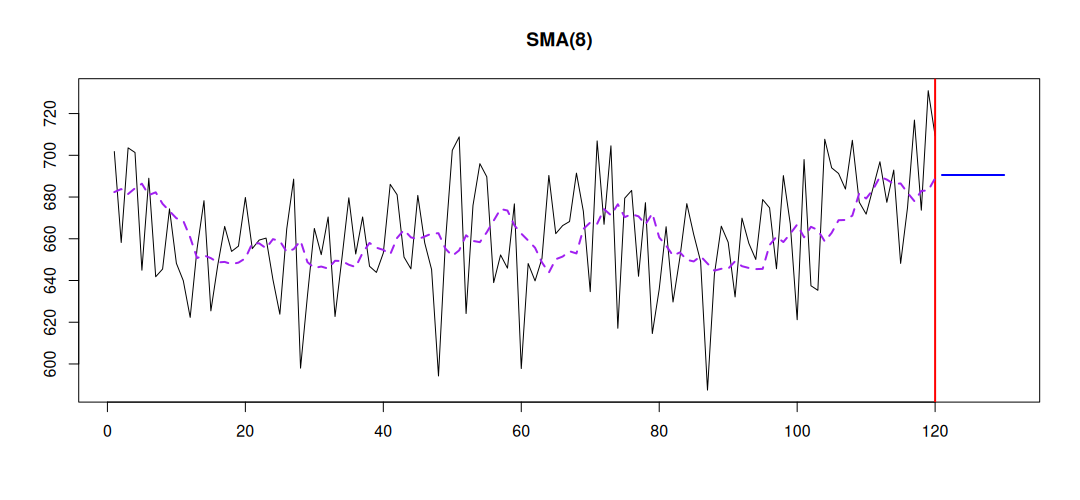
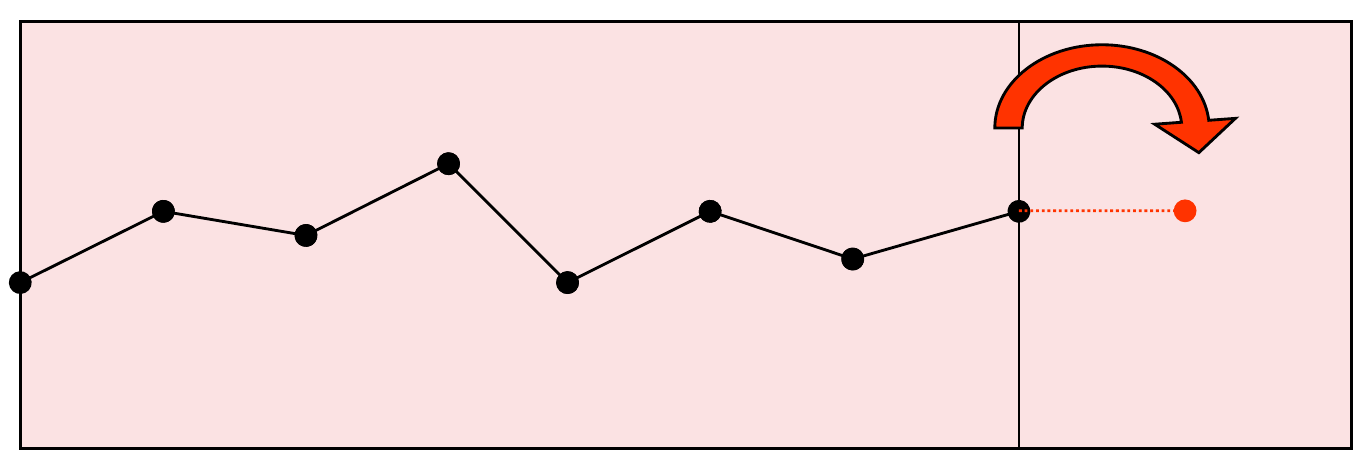
Simple Moving Average of order 8

And here is another forecasting method that is hard to beat in practice. In a recent competition, it gave data scientists huge headaches and even outperformed some powerful ML methods. What’s the name of this beast?! Simple Moving Average! The idea behind the Simple Moving Average (SMA) is to take the average of the last … Read more
Five assumptions behind “forecastability”

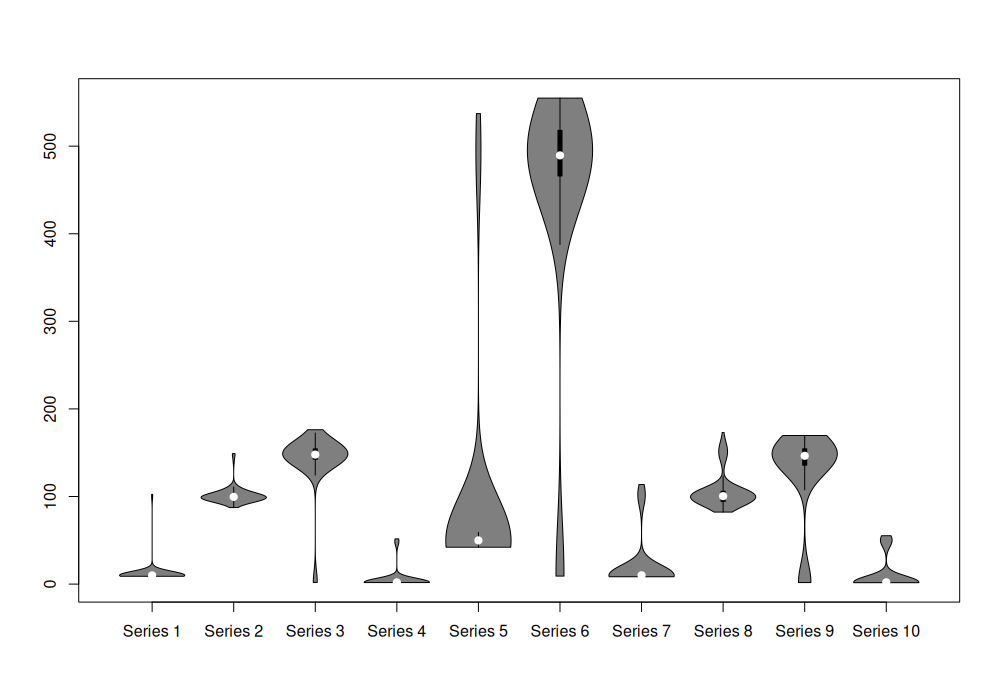
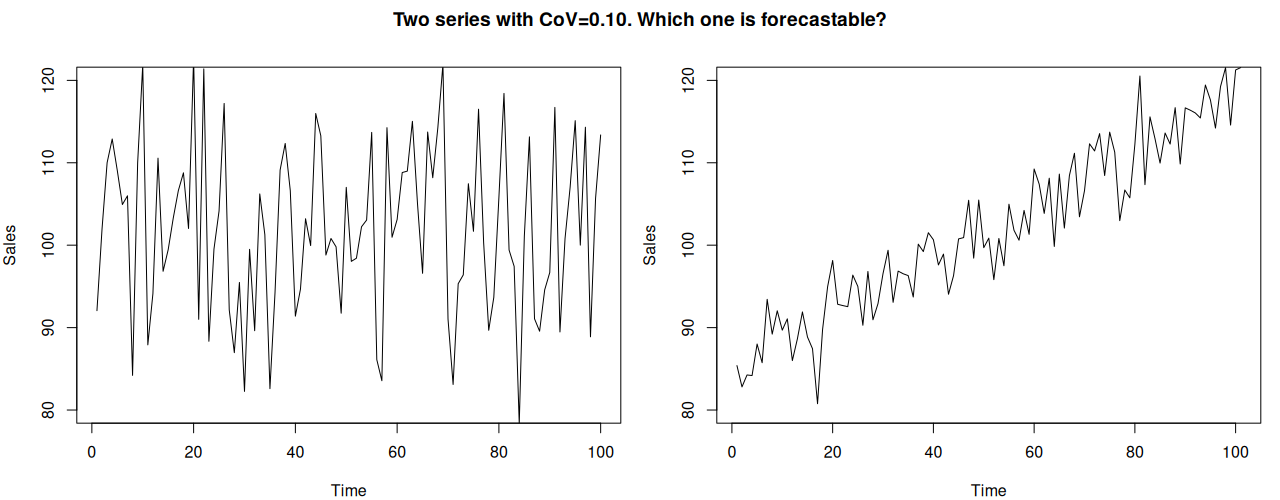
Example of two time series with exactly the same coefficient of variation

Here is a confession. I don’t like the idea of “forecastability”. I think it does not bring value and can be harmful in some cases. Let me explain. One of the definitions I see on the internet: “A measure of the degree to which something may be forecast with accuracy”. This definition is so disturbing … Read more

Another important Naïve method

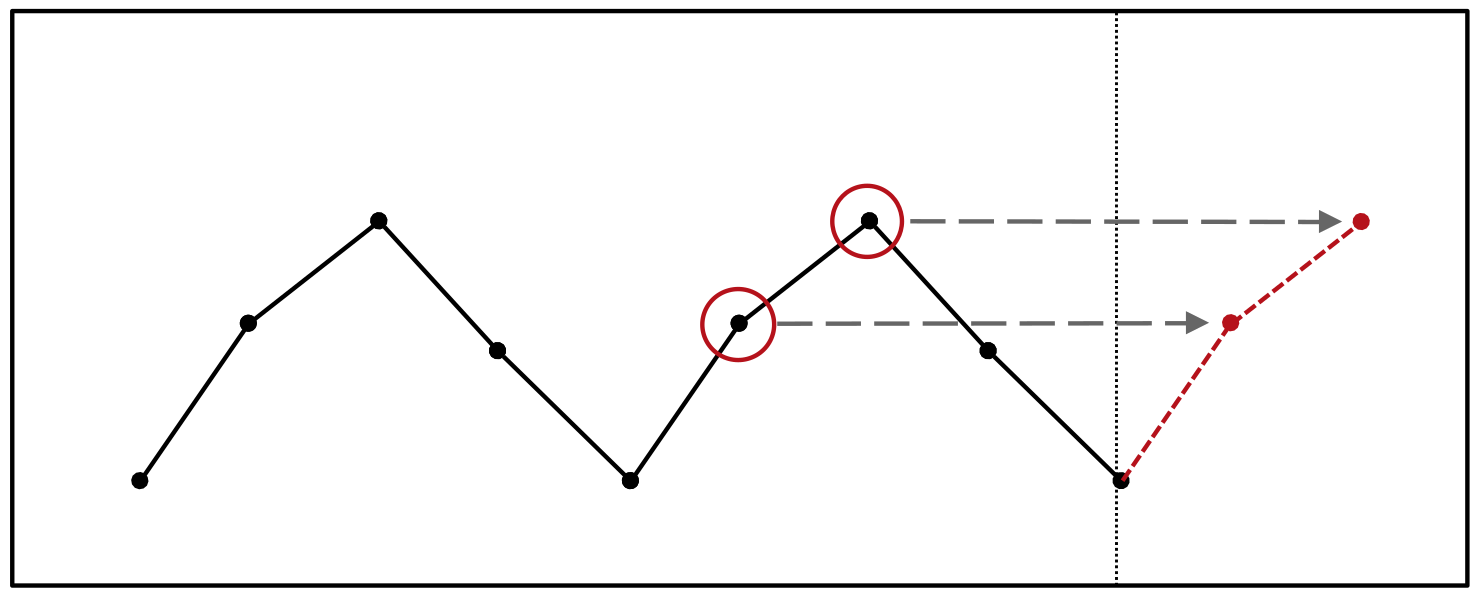
Seasonal Naive depiction

There is another forecasting method that is extremely popular, hard to beat, and has no parameters to estimate. It also has “Naïve” in its name. Do you know what I’m talking about? It is called “Seasonal Naïve”. While the simple Naïve copies the last observed actual into the future as a forecast, the seasonal one … Read more

Why Naïve is popular and important

How Naive works

There is one forecasting method that appears more often than any other in competitions and evaluations. An experienced forecaster will always use it as a benchmark. This method is called “Naïve”, and here is why it is popular and important. Naïve is a very simple forecasting method: the forecast equals to the last observed value. … Read more

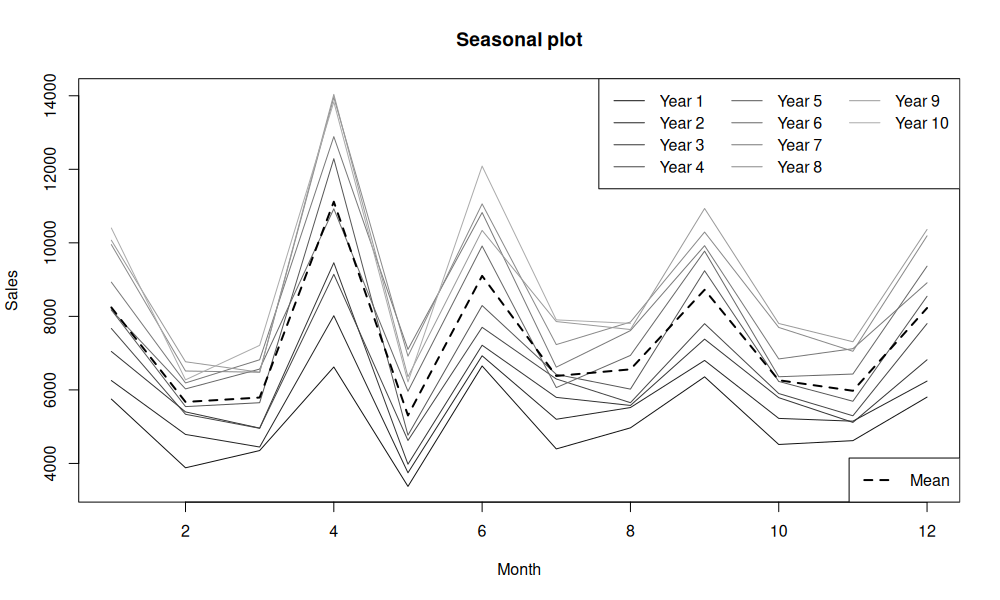
Hans Levenbach’s classification scheme for trend/seasonal components

Seasonal profile of the data

Here is a curious idea: if we can somehow estimate the importance of trend/seasonal components for your data, you can use this in model building and forecasting. But how can we do this first step? Hans Levenbach has an answer with his simple EDA technique. Let me explain. The core idea is simple and neat. … Read more

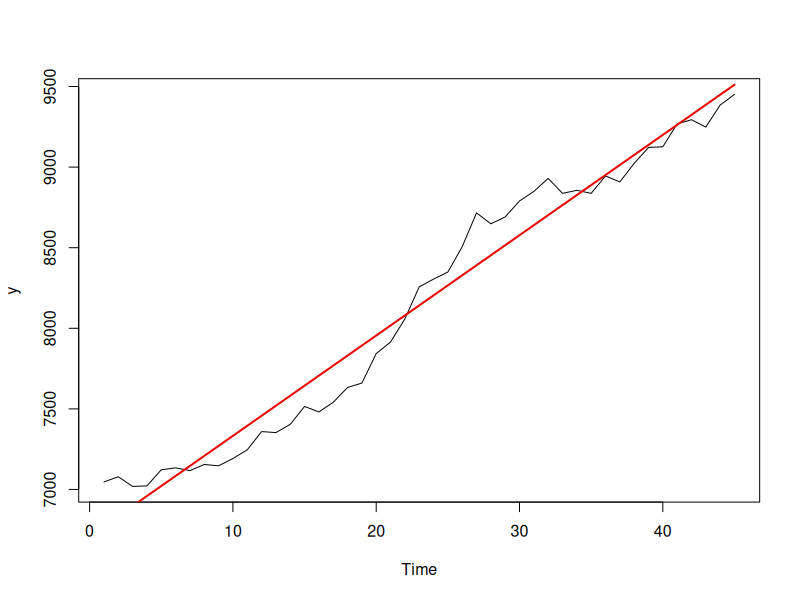
There’s no such thing as “deterministic forecast”

Sometimes I see people referring to a “deterministic” forecast, and I have some personal issues with this. Because if you apply a model to data then there is nothing deterministic about your forecasts! In many contexts, “deterministic” has a precise meaning: no randomness, no uncertainty. A deterministic solution to an optimisation problem (e.g. linear programming) … Read more

Risky business: how to select your model based on risk preferences

A distribution of some error measures across models

What do you use for model selection? Do you select the best model based on its cross-validated performance, or do you use in-sample measures like AIC? If so, there is a way to improve your selection process further. JORS recently published the paper of Nikos Kourentzes and I based on a simple but powerful idea: … Read more