On differencing of ARIMA in state space

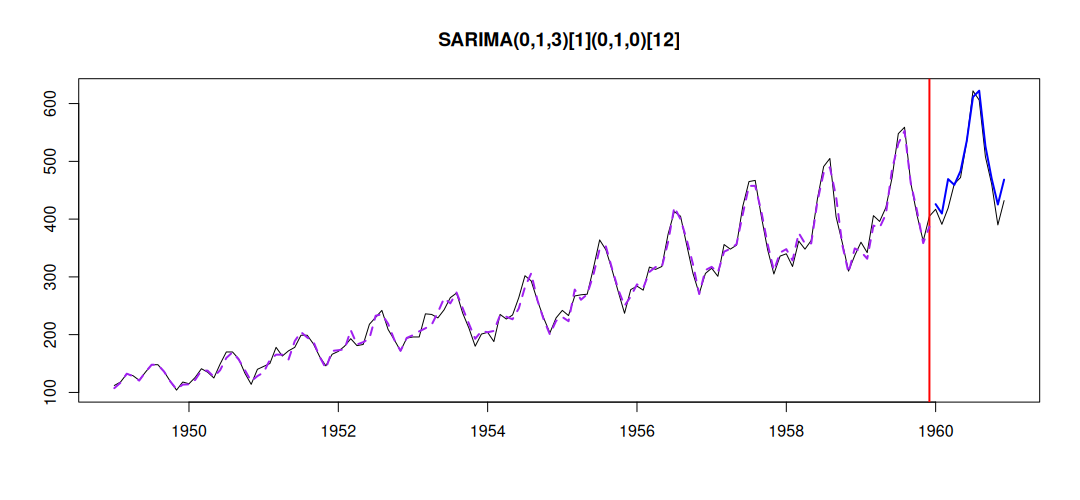
The model fit of MSARIMA

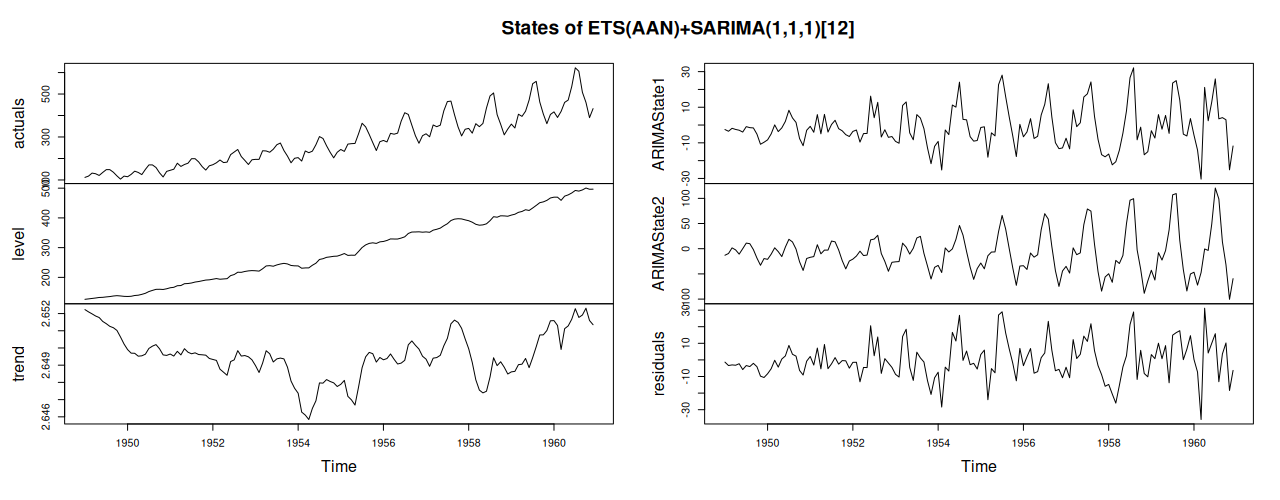
A reader left a comment under the MSARIMA post on LinkedIn saying that in order to compare ARIMAs via information criteria, we need to make sure that the candidate models have the same order of differencing. They are right — for the conventional ARIMA. BUT! In the state space formulation, the problem disappears. Here is … Read more

smooth in python: Multiple Seasonal ARIMA

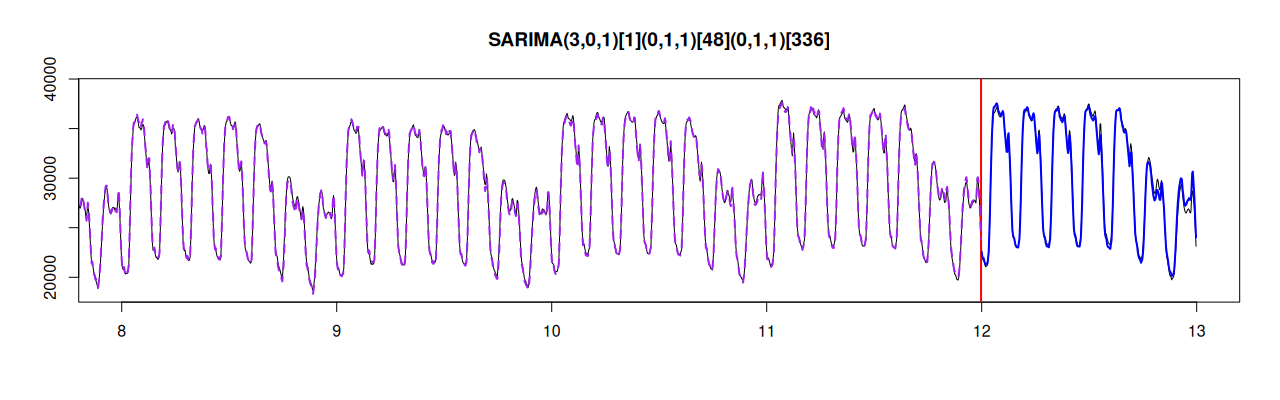
MSARIMA model fit and point forecast

ARIMA has been a workhorse for decades. But the standard implementations quietly hard-code assumptions: one seasonal cycle, Gaussian errors, regressors handled separately etc. This is fine for textbook well-behaved data. But what do you do when you face real data? The conventional implementations (statsmodels or pmdarima in Python, stats in R) do their job well: … Read more

smooth in python: Multistep losses

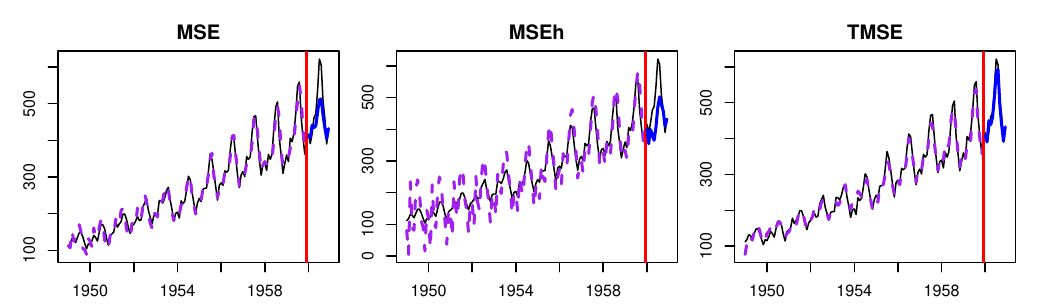
Example of fits of ETS with several multistep losses

Why train a forecasting model on one-step-ahead errors when you care about 10-step-ahead accuracy? This is the core motivation behind multistep losses in dynamic models. This has connection with the so-called “direct forecasting strategy”. And here what it is and how to work with it in Python. Conventional maximum likelihood estimation minimises one-step-ahead errors. It … Read more

smooth v4.3.0 in R: what’s new and what’s next?

Sticker of the smooth package for R

Good news! The smooth package v4.3.0 is now on CRAN. And there are several things worth mentioning, so I have written this post. New default initialisation mechanism Since the beginning of the package, the smooth functions supported three ways for initialising the state vector (the vector that includes level, trend, seasonal indices): optimisation, backcasting and … Read more

Fundamental Flaw of the Box-Jenkins Methodology

Sarah by Yegor Kamelev

If you have taken a course on forecasting or time series analysis, you’ve probably heard of ARIMA and the Box–Jenkins methodology. In my opinion, this methodology has a fundamental flaw and should not be used in practice. Here’s why. When Box and Jenkins wrote their book back in the 1960s, it was a very different … Read more

Multistep loss functions: Geometric Trace MSE

While there is a lot to say about multistep losses, I’ve decided to write the final post on one of them and leave the topic alone for a while. Here it goes. Last time, we discussed MSEh and TMSE, and I mentioned that both of them impose shrinkage and have some advantages and disadvantages. One … Read more

Detecting patterns in white noise

Back in 2015, when I was working on my paper on Complex Exponential Smoothing, I conducted a simple simulation experiment to check how ARIMA and ETS select components/orders in time series. And I found something interesting… One of the important steps in forecasting with statistical models is identifying the existing structure. In the case of … Read more

What does “lower error measure” really mean?

“My amazing forecasting method has a lower MASE than any other method!” You’ve probably seen claims like this on social media or in papers. But have you ever thought about what it really means? Many forecasting experiments come to applying several approaches to a dataset, calculating error measures for each method per time series and … Read more